
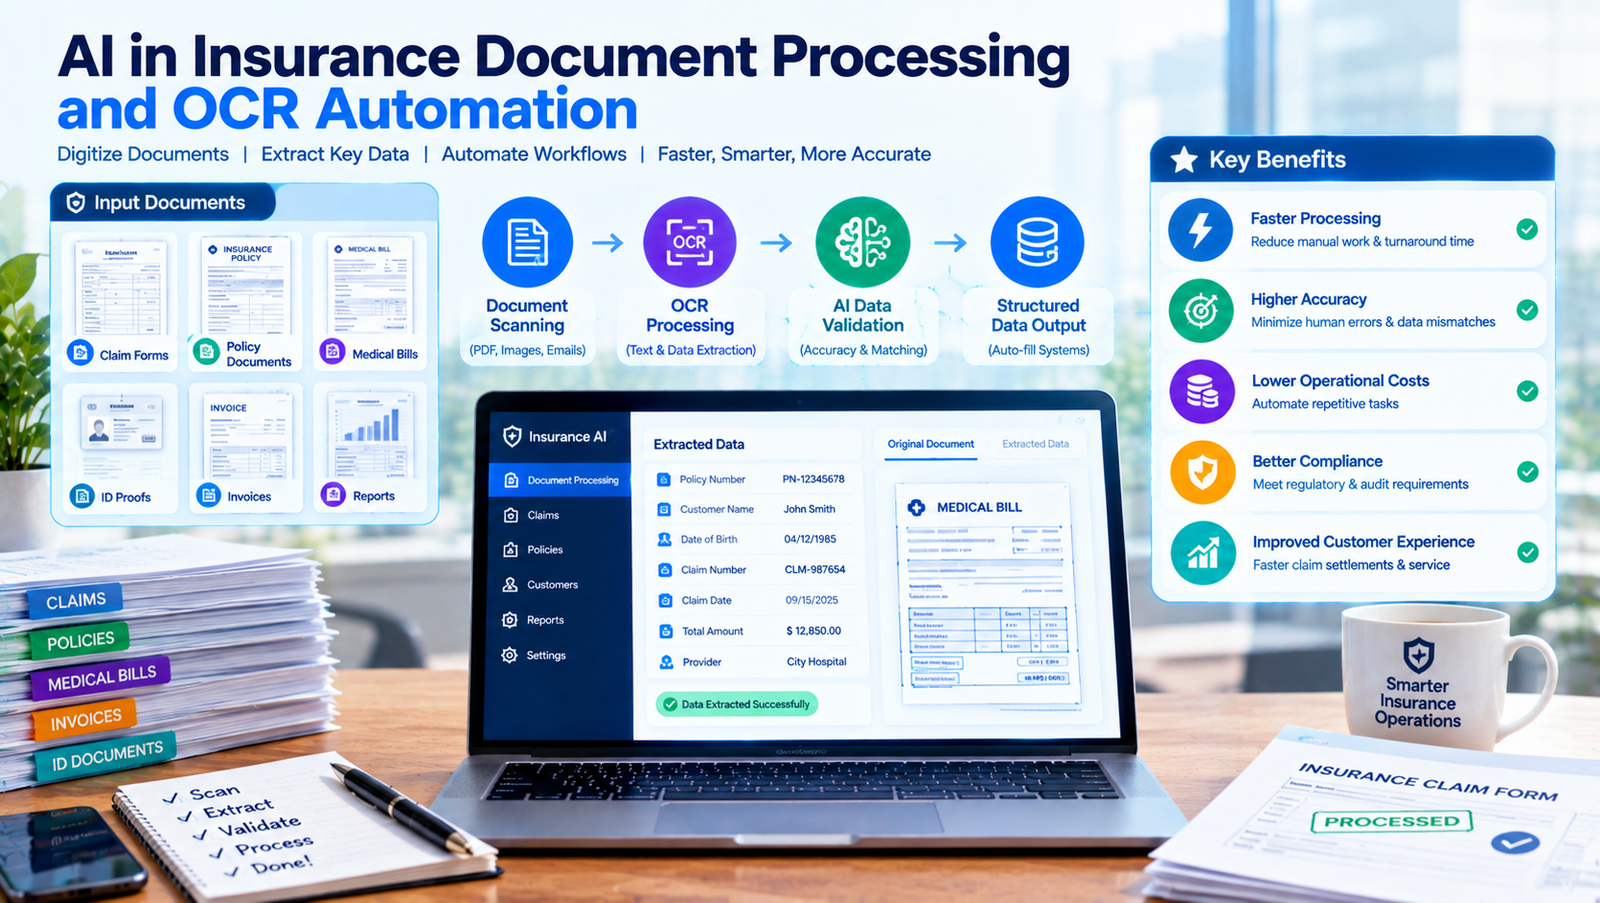
Primary topic: AI in Insurance Document Processing and OCR Automation: Research, Applications, Risks & Future
Research focus: Intelligent document processing, optical character recognition, insurance claims automation, policy document extraction, underwriting, claims validation, fraud detection, document classification, multimodal AI, human-in-the-loop review and insurance workflow modernization
Why Insurance Document Processing Needs AI
Insurance operations are built around evidence. A motor insurance claim may contain an accident report, photographs, a repair estimate, an invoice and a policy schedule. A health insurance claim may include a claim form, hospital bill, discharge summary, prescription, diagnostic report and proof of coverage. A commercial insurance submission may contain financial statements, property schedules, risk surveys, contracts and supporting correspondence.
These documents rarely follow one universal structure. Two hospitals may issue bills with different layouts, while brokers may submit applications using their own templates. A customer may upload a clear PDF, a mobile photograph with shadows, or a scan where important fields are difficult to read. Documents can also contain conflicting values, missing pages, duplicate records or information that does not match the insurer’s existing systems.
Manual processing requires employees to open files, identify document types, locate relevant fields, re-enter information and compare it with policy or claim records. This creates delays and makes quality dependent on the consistency of human review.
AI can help by automating repeatable document tasks and routing uncertain cases to trained staff. The most useful systems connect document understanding directly to insurance workflows rather than stopping after text extraction.
From OCR to Intelligent Document Processing
OCR converts text in an image or scanned document into machine-readable characters. It is an important foundation, but insurance automation requires several additional capabilities.
Email, portal, PDF, scan
Deskew, denoise, crop
Text, tables, fields
Classify and extract
Policy and data checks
Route, review, update
An intelligent document processing system may include:
- OCR and handwriting recognition to read printed or handwritten content
- Document classification to identify claim forms, invoices, policies, medical records and other document types
- Layout understanding to interpret tables, labels, checkboxes, sections and relationships between fields
- Information extraction to capture policy numbers, dates, amounts, names, diagnoses, vehicle details and other relevant fields
- Document comparison to identify inconsistencies between submitted evidence and existing records
- Business-rule validation to check required fields, totals, dates, coverage and other defined conditions
- Workflow automation to send complete, reliable records to the next processing stage
- Human review for low-confidence extraction, conflicting evidence and consequential decisions
The distinction matters. A system can read a policy number correctly and still associate it with the wrong claim. Strong automation must preserve the relationship between the document, extracted field, customer, policy and transaction.
Research Study: Digitizing Health Insurance Documents for Cashless Claim Settlement
A 2024 paper published in Procedia Computer Science proposed an Intelligent Document Management System for digitizing documents used in health insurance claim settlement. The research focused on three document categories: Aadhaar cards, PAN cards and hospital invoices. It explored how extracted information could be converted into structured JSON or CSV data for use in a digital claim workflow.
The reported results showed an extraction accuracy of 94.09% for hospital invoices using AWS services. The paper reported 83.13% for Aadhaar cards and 70.3% for PAN cards using its heuristic approach. These differences are important because document type and extraction method can materially affect performance.
The study illustrates why insurance document automation should be tested separately for each document category. An invoice contains line items, totals and vendor details, while an identity document has a different layout and different critical fields. A single headline accuracy figure can hide weaknesses in specific fields or document types.
For an insurer, the practical lesson is to measure field-level accuracy for high-impact information such as policy identifiers, invoice totals, dates and identity details. Extracted values should also be checked against existing records before they trigger a claim or payment action.
Research source: Digitization of Health Insurance Documents for the Cashless Claim Settlement Using Intelligent Document Management System, 2024
Research Study: RPA and OCR for Insurance Claim Review
A 2026 study published in BMJ Health & Care Informatics evaluated a robotic process automation system that combined OCR with electronic medical record data to identify missing codes during insurance claim post-review at a tertiary hospital.
The system compared 532 surgical procedure codes with 21 cutting-device codes and flagged discrepancies for review. During the reported implementation period, it analyzed 61 claim statements and performed 199 OCR processes. Google Cloud Vision achieved 100% detection accuracy in this particular task, with no false positives reported, while Tesseract produced lower accuracy.
The system reduced average processing time from 120 minutes for manual review to 54 minutes, a reported 55% reduction. The result is especially relevant because it measures an operational workflow rather than OCR performance in isolation.
However, the study was a single-center implementation with a specific code-checking task. Its reported accuracy should not be treated as proof that the same OCR engine will achieve 100% accuracy across all insurers, document formats or claim types.
The broader lesson is that OCR can create measurable value when it is connected to a clearly defined insurance control. The best initial use cases are often narrow, repetitive checks where the expected answer can be validated against a reliable reference system.
Research source: Robotic Process Automation for Identifying Missing Codes on Insurance Claims, BMJ Health & Care Informatics, 2026
Research Study: OCR and RAG for Medical Insurance Post-Claims
A 2025 IEEE conference paper, Automation of Medical Insurance Post-Claims using OCR and RAG Models, proposed a system combining OCR with retrieval-augmented generation and vector databases. The intended workflow extracts information from medical bills, retrieves relevant information and supports checks for inconsistencies and possible fraud indicators.
This approach addresses a common weakness in document automation. OCR can extract a value from a bill, but the system still needs relevant context to determine whether that value is expected. A retrieval system can bring the appropriate policy wording, claim rules or supporting record into the verification process.
For example, an AI system could extract a billed service and amount, retrieve the applicable policy provisions, and present the relevant clauses alongside the extracted evidence. This can help an employee review the claim without searching through multiple files manually.
RAG does not guarantee that a conclusion is correct. The retrieved policy version may be outdated, the extracted clause may be incomplete, or the model may misinterpret an exclusion. A production system should therefore show the source document, relevant page and policy version supporting each material finding.
The paper supports a practical architecture in which OCR provides document content, retrieval provides evidence and the workflow applies controlled validation. The available abstract describes improvements in speed and accuracy but does not provide enough numerical detail to establish a general performance benchmark.
Research source: Automation of Medical Insurance Post-Claims using OCR and RAG Models, IEEE COMPSAC 2025
Research Study: NLP for Insurance Claims and Prior Authorization
A paper presented at the 2025 International Conference on Applied Artificial Intelligence and Computing describes a multi-model approach to insurance claims and prior authorization processing. Its proposed architecture combines LSTM models for structured claim and policy information, RoBERTa for digital text, OCR for scanned documents and ResNet for visual evidence.
The significance of this work is its use of different AI methods for different data types. Insurance files may contain structured fields, written descriptions, scanned pages and photographs. Treating all of these as plain text can discard useful information.
In a motor claim, for example, the system may need to read the claim form, interpret the adjuster’s notes and analyze photographs of vehicle damage. In health insurance, it may need to extract a billing code while also interpreting supporting medical documentation. A multimodal pipeline can combine these sources, provided each source remains traceable.
The paper describes a feature-fusion approach, in which information from different models is combined to support downstream analysis. This is a useful design direction for insurers with document-heavy processes, although the available source excerpt does not establish a broadly generalizable operational accuracy figure.
Research source: Natural Language Processing for Improving Insurance Claims and Prior Authorization Processing, ICAAIC 2025
Research Study: Multimodal AI for Insurance Claims Adjudication
A 2025 conference paper published in the proceedings of the 2025 International Conference on Artificial Intelligence, Systems and Network Security describes a multimodal large language model framework for insurance claims adjudication. The proposed framework combines policy-document understanding with visual damage assessment.
Its design includes a policy constraint understanding module, a visual damage reasoning unit and a decision consistency verifier. The first component represents policy clauses and compares them with claim information. The second analyzes images of vehicle damage. The third checks whether the proposed outcome is consistent with the policy constraints and visual evidence.
The authors report an 8.2% improvement in adjudication accuracy compared with existing methods. This is a result reported by the paper, not a universal estimate of what insurers should expect from multimodal AI. The available publication details do not establish that the same improvement will transfer to other claim portfolios, policy types or production environments.
The study is nevertheless relevant because it addresses a real insurance problem: claim decisions often depend on more than one evidence format. A document-only system may read the policy correctly but fail to interpret damage photographs, while a vision-only model may identify damage without understanding coverage exclusions.
The practical implication is to connect visual evidence and policy interpretation while preserving separate evidence trails for each.
Research source: MMLM-CA: A Multimodal Large Language Model Framework for Automated Insurance Claims Adjudication, 2025 conference proceedings
Research Study: AI-Enhanced Process Automation in Insurance
A 2025 research paper on arXiv examined AI-enhanced business process automation in an insurance setting using object-centric process mining. The case study considered the use of a large language model in production to automate the identification of claim parts, a task that had previously been performed manually and had become a bottleneck.
The research is useful because it looks beyond the model itself and examines how AI changes the wider process. Automation can increase capacity, but it can also create new handoffs, exception queues and review requirements. If a model processes documents quickly but sends too many uncertain cases to employees, the overall workflow may not improve as much as expected.
Process mining can help insurers compare the real workflow before and after automation. It can reveal where documents wait, which claim types require repeated handling, and whether automated extraction actually shortens end-to-end processing time.
For implementation teams, this suggests measuring the full claim journey rather than reporting only OCR speed or model accuracy.
Research source: AI-Enhanced Business Process Automation: A Case Study in the Insurance Domain Using Object-Centric Process Mining, 2025
Where AI Document Processing Creates Value in Insurance
Claims Intake and Document Classification
Claims intake is a natural starting point because insurers receive many document types through email, web portals, mobile applications, brokers and third-party administrators. AI can identify the type of document, associate it with a claim and check whether required evidence is present.
The system can also identify duplicate submissions, detect unreadable pages and route documents to the correct team. A claim containing all required evidence can move forward, while an incomplete submission can trigger a request for missing information.
Claims Data Extraction and Validation
AI can extract policy numbers, dates of loss, claimant details, invoice amounts, provider information, vehicle identifiers and other claim-specific fields. Validation rules can compare these fields against policy administration systems, customer records and claim histories.
The goal is not to accept every extracted value automatically. Low-confidence fields, conflicting values and unusual amounts should be routed for review.
Underwriting and Risk Assessment
Underwriters may need to review applications, financial statements, inspection reports, property schedules, medical information and broker submissions. AI can organize these documents, extract relevant facts and identify missing or inconsistent information.
For commercial underwriting, the system could compare declared property values across schedules and supporting documents. For personal lines, it could extract relevant application details and flag mismatches with existing records.
AI should support the underwriter’s evidence review rather than silently make consequential coverage or pricing decisions from unverified extracted data.
Policy Administration and Renewals
Policy documents contain coverage limits, exclusions, endorsements, deductibles, effective dates and renewal terms. AI can extract these details into structured records and compare them with previous policy versions.
This can help employees identify changed terms, missing endorsements and inconsistencies between the policy document and the administration system. Version control is essential because an accurate extraction from an obsolete policy can still lead to a wrong decision.
Fraud Detection and Claims Investigation
Document AI can identify inconsistencies that deserve further investigation, such as conflicting dates, repeated invoice identifiers, mismatched names or unusual differences between a claim form and supporting evidence.
These signals should be treated as indicators, not proof of fraud. A mismatch may result from a clerical error, a legitimate correction or a document issued by a third party. Investigators need access to the original evidence and a clear explanation of why the system raised the alert.
Visual: The Insurance Document Intelligence Stack
Claims forms, invoices, policies, photos, reports and correspondence
OCR, handwriting recognition, image enhancement and layout analysis
Classification, entity extraction, document comparison and summarization
Confidence thresholds, policy rules, validation and exception handling
Claim systems, underwriting, policy administration, audit and customer communication
This architecture separates reading, interpretation, validation and action. That separation makes it easier to test each component and identify where an error occurred.
Document Types and Suitable AI Capabilities
| Document type | Useful AI capability | Validation requirement |
|---|---|---|
| Claim forms | OCR and field extraction | Required fields and policy match |
| Invoices and bills | Table extraction and arithmetic checks | Line items, totals and duplicates |
| Policy documents | Clause extraction and semantic search | Policy version and source citation |
| Medical reports | Clinical text extraction and classification | Context, terminology and authorized review |
| Damage photographs | Computer vision and image comparison | Image quality and adjuster confirmation |
| Broker submissions | Document classification and summarization | Completeness and source reconciliation |
| Identity documents | OCR and document authenticity checks | Identity verification and fraud controls |
Why OCR Accuracy Alone Is the Wrong KPI
An OCR engine may achieve strong character recognition and still fail to deliver a reliable insurance workflow. A single incorrect digit in a policy number can associate a document with the wrong customer. A misplaced decimal point can change an invoice amount. A date extracted from the wrong section can distort the claim timeline.
Insurers should therefore measure several levels of quality.
Were the characters and words read correctly?
Were important values extracted correctly?
Were the fields linked to the correct claim and policy?
Did the system route or update the case correctly?
The final measure should be whether the complete process produces reliable, auditable results. A system that extracts 98% of fields correctly may still require substantial manual work if the remaining errors affect critical fields or if the system cannot detect uncertainty.
Generative AI and Retrieval-Augmented Generation in Insurance
Large language models can help summarize claim files, compare policy wording, explain discrepancies and prepare case notes. Retrieval-augmented generation can ground these responses in approved policy documents, claims procedures and internal guidance.
A safe workflow should retrieve the relevant source, identify the applicable version, quote or summarize the relevant passage, and show the supporting document to the reviewer. The model should not invent missing policy clauses or fill gaps in evidence with assumptions.
For example, an adjuster reviewing a claim could ask the system to summarize the submitted evidence and identify which documents support each key fact. The output should distinguish information directly extracted from a document from conclusions inferred by the model.
Generative AI is particularly useful for reducing the time spent searching and summarizing. It should not be treated as an independent authority on coverage, liability or payment.
Legacy System Integration and Data Architecture
Many insurers operate separate platforms for claims, policy administration, underwriting, customer relationship management, document storage and finance. Document automation creates value only when extracted data reaches the right system with appropriate controls.
A practical integration architecture should include:
- API integration for sending validated fields to claims and policy systems
- Document storage integration to preserve original files and processed versions
- Metadata management for claim ID, policy ID, document type, source and processing status
- Event-driven workflows to trigger the next action when a document is received or validated
- Exception queues for low-confidence extraction and unresolved conflicts
- Audit logs recording model version, extracted values, corrections and final actions
The original document should remain available throughout the process. Each extracted field should retain a link to its source page or region wherever technically feasible. This evidence lineage is especially important when a claim is disputed or a regulator asks how a decision was reached.
Security, Privacy and Governance
Insurance documents can contain personal identifiers, financial information, medical records, property details and other sensitive data. AI document processing therefore requires strong security controls.
The implementation should address:
- Encryption in transit and at rest
- Role-based access to documents and extracted data
- Data minimization and purpose limitation
- Retention and deletion policies
- Vendor access and subcontractor controls
- Data residency and cross-border transfer requirements
- Model training restrictions for customer documents
- Audit trails and incident response
- Testing for bias and uneven extraction performance across document types
Insurers should also test performance on poor-quality scans, different languages, varied templates, handwritten fields and documents from different regions. A system trained mainly on clean, standardized forms may perform poorly on the documents that create the greatest operational burden.
Implementation Roadmap
Identify document volumes, formats, systems, manual touchpoints, error types and the cost of rework. Choose a process with clear rules and measurable outcomes.
Collect appropriately authorized examples covering clean scans, poor images, different templates and common exceptions. Establish a human-verified ground truth.
Measure field-level precision, recall, exact-match accuracy, confidence calibration and error severity. Test against documents not used during development.
Run AI alongside the existing process. Compare results, capture reviewer corrections and confirm that automation reduces total handling time without increasing downstream errors.
Connect validated outputs to business systems, maintain exception queues and monitor accuracy, drift, security and workflow outcomes.
Expert Recommendation
Insurers should begin with a document workflow where the task is repetitive, the expected output can be checked and errors can be caught before a consequential decision is made. Examples include document classification, invoice field extraction, missing-document detection, duplicate identification and comparison of extracted values against existing records.
Avoid starting with a fully autonomous claims adjudication system. Begin by helping employees process evidence faster, then expand automation as the organization accumulates reliable evaluation data and operational experience.
The recommended design is a controlled pipeline:
- Use OCR for text and layout extraction
- Use specialized AI models for document classification and field extraction
- Use deterministic rules for arithmetic, required fields and policy-system checks
- Use retrieval-based language models for policy search and evidence summaries
- Use confidence thresholds to decide when human review is required
- Keep final authority with authorized employees for disputed, ambiguous or high-impact cases
- Preserve source documents and a traceable record of every material output
The most important investment may not be the largest model. It may be the quality of the document dataset, the reliability of integration, the design of exception handling and the ability to measure the entire workflow.
Expert Perspective
A useful principle for insurance AI is that documents must be decision-ready, not merely digitized. A recent industry perspective on financial-services AI makes this distinction directly: scanning creates an image and OCR creates text, but reliable decision-making also requires classification, extraction, validation, correlation and traceability.
This is a practical recommendation rather than a guarantee of performance. The source emphasizes that important data points should remain connected to the documents and fields from which they were extracted, with governance and human intervention built into the process.
Source: Before AI Makes Decisions, BFSI Must Make Its Documents Decision Ready, September 2026
KPIs for Insurance Document Automation
| KPI | What it measures | Why it matters |
|---|---|---|
| Field-level accuracy | Correctly extracted critical fields | Protects downstream decisions |
| Straight-through processing rate | Documents completed without manual intervention | Measures practical automation |
| Exception rate | Documents sent for human review | Shows where the model struggles |
| End-to-end cycle time | Time from receipt to completed processing | Measures business impact |
| Rework rate | Cases requiring correction or repeated handling | Captures hidden process costs |
| Cost per document | Technology and labor cost per completed item | Supports ROI analysis |
| Traceability coverage | Outputs linked to source evidence | Supports audits and disputes |
Future Predictions: 2027–2030
2027: Document AI Moves from Extraction to Evidence Validation
Insurers will increasingly evaluate document systems by whether they can validate information against policies, claims records and supporting evidence. OCR will remain a core capability, but competitive differentiation will come from linking extracted data to reliable workflow actions.
2028: Multimodal Claims Workflows Expand
More claims workflows will combine text, tables, photographs and structured system data. Motor claims are a natural use case because the evidence may include policy wording, accident descriptions, repair estimates and images. Health claims may combine bills, clinical records and policy conditions. Human review will remain important when sources conflict.
2029: Policy-Aware Document Assistants Become More Common
Retrieval-augmented systems will increasingly help claims handlers and underwriters find relevant clauses, compare document versions and prepare evidence summaries. Strong implementations will cite the exact source document and policy version rather than provide unsupported answers.
2030: Insurance Operations Become More Event-Driven
Document processing may become a continuous part of insurance operations. When a new document arrives, the system could classify it, extract fields, compare it with existing records, identify missing evidence and trigger the next workflow step. More complex cases will be routed to specialists with a structured evidence package already prepared.
These are forward-looking scenarios, not guaranteed outcomes. Adoption will depend on document quality, integration costs, regulation, model reliability and insurers’ willingness to redesign legacy workflows.
Startup Opportunities
AI document processing offers opportunities for specialized insurance technology products, especially where general-purpose OCR does not understand industry-specific evidence.
- Insurance Claims Document AI: Extract and validate claim information across forms, invoices and supporting reports
- Policy Comparison AI: Compare policy versions, endorsements, exclusions and renewal changes
- Medical Bill Validation: Extract line items and compare them with claim rules and supporting records
- Broker Submission Automation: Classify underwriting submissions and identify missing information
- Multimodal Motor Claims AI: Combine claim documents, repair estimates and damage photographs
- Document Fraud Signals: Detect duplicates, inconsistencies and suspicious document patterns for investigation
- Insurance RAG Copilot: Answer staff questions using approved policy and procedure documents with citations
- Legacy Document Integration: Connect scanned archives and older systems to modern claims platforms
A defensible product should focus on one document-heavy workflow, demonstrate measurable end-to-end improvement and provide reliable evidence lineage. A generic chatbot layered over a document repository is less valuable than a system that understands a specific insurance process and safely moves validated information into the insurer’s operations.
Frequently Asked Questions
What is AI in insurance document processing?
AI in insurance document processing uses OCR, machine learning, language models and workflow automation to classify documents, extract information, validate evidence and route cases through insurance operations.
What is the difference between OCR and intelligent document processing?
OCR converts text in images into machine-readable text. Intelligent document processing adds document classification, layout understanding, field extraction, validation, contextual interpretation and workflow integration.
Can AI automate insurance claims?
AI can automate selected claims tasks, including document intake, classification, data extraction, completeness checks and case summarization. Complex or disputed claims may still require an authorized claims professional.
How does AI reduce insurance processing time?
AI can reduce manual document opening, data entry, searching, comparison and routing. The actual improvement depends on document quality, integration, exception rates and the complexity of the workflow.
Can OCR detect insurance fraud?
OCR alone does not detect fraud. It can make document information searchable, while AI and validation systems can identify inconsistencies, duplicates and patterns that warrant further investigation.
Is generative AI reliable for interpreting insurance policies?
Generative AI can help retrieve and summarize policy wording, but it may misinterpret clauses or use the wrong version. Reliable systems should cite source documents, apply validation rules and retain human review for consequential decisions.
What is the biggest challenge in insurance OCR automation?
The main challenge is producing reliable, correctly linked and traceable information across varied document formats. High character-recognition accuracy is not enough if extracted values are associated with the wrong policy or trigger an incorrect workflow action.
Final Perspective
AI in insurance document processing is not simply a project to replace manual typing with OCR. It is an opportunity to improve how insurers collect, interpret, validate and use evidence.
The research illustrates several distinct paths to value. The 2024 health insurance document study demonstrates the importance of testing extraction performance by document type. The 2026 BMJ implementation shows how OCR connected to a narrowly defined claims control can reduce processing time. Research on OCR and retrieval-augmented generation points toward policy-aware verification, while multimodal claims research shows how documents and images can be evaluated together. Process-mining research adds another lesson: automation must be assessed across the entire workflow, not only at the model level.
For insurers, the most reliable approach is to build a controlled document intelligence layer that connects original evidence to structured data, validation rules and business systems. It should know when to proceed, when to ask for missing information and when to send a case to a human reviewer.
The core transformation is:
The insurers that gain lasting value will be those that combine accurate extraction with process redesign, source-level traceability, secure integration and meaningful human oversight. The objective is not to automate every decision. It is to make routine work faster, evidence easier to find and consequential decisions more consistent and defensible.
Research Sources
- Digitization of Health Insurance Documents for the Cashless Claim Settlement Using Intelligent Document Management System, Procedia Computer Science, 2024
- Robotic Process Automation for Identifying Missing Codes on Insurance Claims, BMJ Health & Care Informatics, 2026
- Automation of Medical Insurance Post-Claims using OCR and RAG Models, IEEE COMPSAC 2025
- Natural Language Processing for Improving Insurance Claims and Prior Authorization Processing, ICAAIC 2025
- MMLM-CA: A Multimodal Large Language Model Framework for Automated Insurance Claims Adjudication, 2025 conference proceedings
- AI-Enhanced Business Process Automation: A Case Study in the Insurance Domain Using Object-Centric Process Mining, 2025
- Before AI Makes Decisions, BFSI Must Make Its Documents Decision Ready, September 2026
- ABBYY, AI Document Processing: OCR, Classification, Extraction and Human Review
- Everest Group, Beyond Words: Unveiling the True ROI of Intelligent Document Processing

Leave a Reply