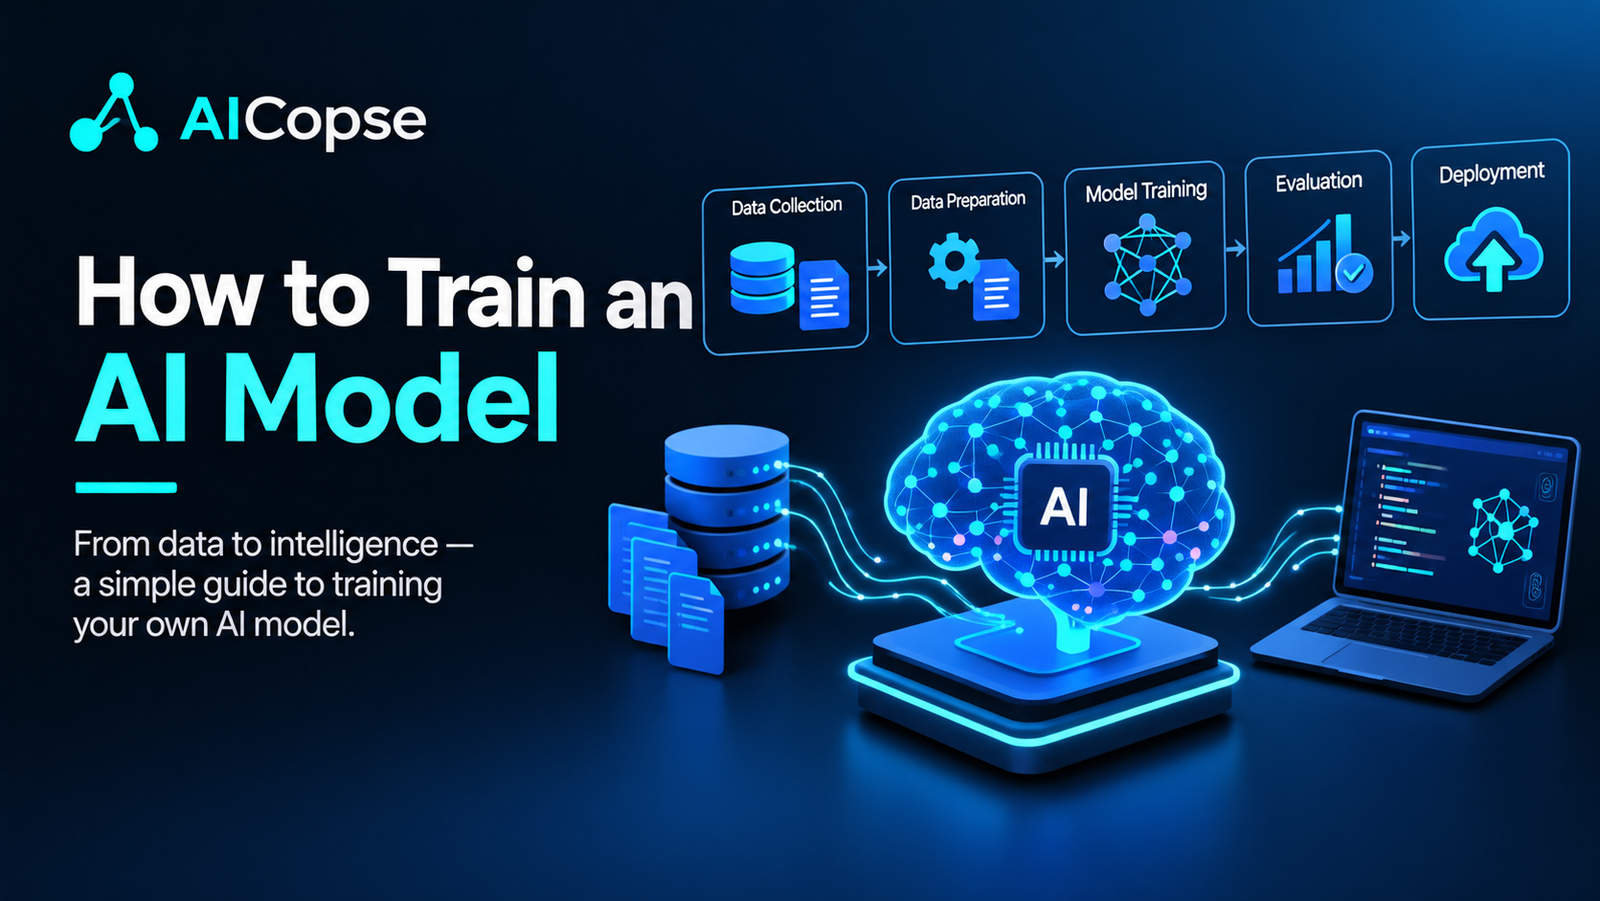
“Training an AI model” sounds like something only big labs do with thousands of chips. In reality it covers a wide range, from a spam filter you can train on a laptop in seconds to a frontier language model that costs hundreds of thousands of GPU-hours. Most beginners should not start at the expensive end, and most businesses should not train from scratch at all.
This guide explains what training actually is, how to decide whether you need it, and the ten steps that every training project follows. You will run real code, see why a learning rate that is too high destroys a model, watch overfitting happen in numbers, and learn how to read the signs when training goes wrong.
What Does “Training” Mean?
Training is the process of adjusting a model’s internal numbers (its parameters) so that its predictions get closer to the right answers. A model is just a mathematical function with adjustable knobs. Training turns the knobs, a tiny bit at a time, until the function does the job well. If you are new to the field, our explainer on what machine learning is covers the basics.
The student analogy
The training loop
Almost every model, from a simple line to a giant neural network, learns through the same loop:
Do You Need to Train a Model at All?
This is the most valuable question in the guide, and most tutorials skip it. “Train” can mean four very different levels of effort. Start at the top and move down only when the cheaper option fails:
| Option | What you do | Data needed | Choose it when |
|---|---|---|---|
| 1. Prompt a pretrained model | Write clear instructions and examples. No training. | A handful of examples | The task is language-based and a general model already does it well |
| 2. Add retrieval (RAG) | Give the model your documents at question time. No training. | Your documents | The model lacks your private or changing facts |
| 3. Fine-tune a pretrained model | Continue training an existing model on your examples. | Hundreds to thousands of quality examples | You need a consistent behaviour, format or specialist skill prompts cannot hold |
| 4. Train from scratch | Start from random parameters and learn everything from your data. | Large datasets (small tabular models: thousands of rows; language models: billions of tokens) | Your problem is classic tabular or small-scale ML, or you are a lab building a foundation model |
The rule: for text, images and speech, fine-tuning a pretrained model almost always beats training from scratch, because the model already learned general patterns from huge datasets. For ordinary business tables (customers, prices, transactions), training a small model from scratch is normal and cheap. For a deeper look at the prompt, retrieval and fine-tuning ladder, see our guide on how to optimize AI models.
The 10 Steps of Training an AI Model
| Step | What to do | Done when |
|---|---|---|
| 1. Define the task and the metric | Write one sentence on what the model predicts and how success is measured, plus limits on speed and acceptable errors. | You can state a target such as “catch 90% of fraud with under 5% false alarms” |
| 2. Set a baseline | Measure a simple method first: a rule, an average or the current human process. | You know the score your model must beat |
| 3. Collect data | Gather examples that match real-world conditions, with the correct answers (labels) where needed. | The data represents the cases the model will see |
| 4. Clean and label | Remove duplicates and errors, fix missing values, scale numbers, check label quality. | A sample of the data survives a manual spot check |
| 5. Split the data | Separate training, validation and test sets before any other processing that learns from data. | The test set is locked away |
| 6. Choose a model | Start simple, or start from a pretrained model for text, images and speech. | The choice fits your data type, speed and size limits |
| 7. Train | Run the loop: predict, measure loss, update. Log loss on training and validation data. | Loss is falling and validation scores are tracked |
| 8. Validate and tune | Adjust hyperparameters, fight overfitting and compare with the baseline, using validation data only. | Validation score plateaus above the baseline |
| 9. Test once | Score the final model on the untouched test set and record the result. | You have an honest number, with its uncertainty |
| 10. Deploy and monitor | Save and version the model, serve it, and watch quality and data drift in production. | Alerts and a retraining plan are in place |
Data: The Part That Decides Everything
Practitioners say it constantly because it is true: a model can only learn what its data shows. Better algorithms rarely rescue bad data, and good data often rescues a simple algorithm.
| Data problem | What goes wrong | Fix |
|---|---|---|
| Wrong or noisy labels | The model faithfully learns your mistakes. | Review a sample, use clear labelling rules, have experts check hard cases. |
| Data leakage | Test or future information sneaks into training, giving fake high scores. Duplicates across splits and scaling before splitting are common causes. | Split first, de-duplicate across splits, fit preprocessing on training data only. |
| Unrepresentative data | Works in the lab, fails on real users. | Collect from real conditions, and include hard and rare cases. |
| Class imbalance | With 1% fraud, “never fraud” scores 99% accuracy and catches nothing. | Use precision and recall, resample or weight classes, split with stratification. |
| Missing values and mixed scales | Large-valued features dominate; gaps break training. | Fill or flag missing values; standardise numeric features. |
| Bias in the data | The model repeats historical skew. | Audit by group and test results separately for each. |
How much data do you need?
There is no universal number. It depends on the task, the model and the noise in the data. Use these anchors:
- Test it empirically: train on 25%, 50% and 100% of your data. If the validation score is still climbing at 100%, more data will help. If it plateaued, fix the data or the model instead.
- Fine-tuning needs far less than training from scratch. In the LIMA study, a 65-billion-parameter model fine-tuned on only 1,000 carefully curated examples followed instructions strongly. Quality beat quantity.
- Pretraining language models needs vast text. DeepMind’s Chinchilla research found the best use of a compute budget is roughly 20 training tokens per parameter, so a 7-billion-parameter model wants about 140 billion tokens.
Choosing a Model
Match the model to the data type, start simple and let the baseline tell you whether complexity pays off.
| Your data | Start with | Upgrade to |
|---|---|---|
| Tables (rows and columns) | Logistic or linear regression, decision trees | Gradient-boosted trees such as XGBoost; random forests |
| Images | A pretrained vision model, fine-tuned | Larger architectures if the small one underperforms |
| Text | Prompting a language model, or TF-IDF with a linear model for classification | A fine-tuned pretrained transformer (see our NLP guide) |
| Time series | Simple forecasts and seasonal baselines | Tree models with lag features, then sequence neural networks |
| Speech or audio | A pretrained speech model, fine-tuned on your accents or vocabulary | Domain-specific fine-tuning with more data |
For a wider overview of model families, see our guide to the types of AI.
Example 1: Training from Scratch with Gradient Descent
The code below trains the simplest possible model, a straight line, using nothing but NumPy. The true rule is y = 3x + 2 with some noise, and the model starts knowing nothing. Watch what happens at three different learning rates:
import numpy as np
rng = np.random.default_rng(0)

x = rng.uniform(-1, 1, 200)
y = 3 * x + 2 + rng.normal(0, 0.2, 200)          # truth: y = 3x + 2, plus noise

def train(lr, epochs=100):
    w, b = 0.0, 0.0                               # start knowing nothing
    hist = []
    for _ in range(epochs):
        pred = w * x + b                          # 1. predict
        err = pred - y
        hist.append(np.mean(err**2))              # 2. measure the loss
        w -= lr * 2 * np.mean(err * x)            # 3-4. gradient step and update
        b -= lr * 2 * np.mean(err)
    return w, b, hist

for lr in (0.01, 0.1, 1.05):
    w, b, h = train(lr)
    print(f"lr={lr:<5} loss at epoch 1: {h[0]:.3f}  epoch 10: {h[9]:.3f}  epoch 100: {h[-1]:.3g}  learned w={w:.2f} b={b:.2f}")

# lr=0.01  loss at epoch 1: 8.184  epoch 10: 6.171  epoch 100: 0.77     learned w=1.63 b=1.84
# lr=0.1   loss at epoch 1: 8.184  epoch 10: 0.825  epoch 100: 0.0417   learned w=2.97 b=1.98
# lr=1.05  loss at epoch 1: 8.184  epoch 10: 42.776 epoch 100: 3.41e+10 learned w=-25278.32 b=-204226.74
| Learning rate | Loss after 100 steps | Learned (true: 3 and 2) | Verdict |
|---|---|---|---|
| 0.01 (too small) | 0.77 | 1.63 and 1.84 | Learning, but far too slowly |
| 0.1 (good) | 0.0417 | 2.97 and 1.98 | Recovered the true rule |
| 1.05 (too large) | 34 billion | Huge, nonsense values | Diverged: each step overshot and made things worse |
What this shows: training is just stepping downhill on the loss. The learning rate is the step size. Too small and you crawl, too large and you leap over the valley and fly off. With a good rate, the model found the hidden rule (3 and 2) from noisy examples alone. This same logic, scaled up with calculus tricks for millions or billions of parameters, trains every neural network. Frameworks such as PyTorch and TensorFlow automate steps 3 and 4 so you do not compute gradients by hand.
Example 2: Overfitting in Numbers
A model that is too flexible memorises the training data, noise included, and then fails on new data. The code fits curves of increasing complexity to 30 noisy points from a sine wave, then tests them on 200 fresh points:
from sklearn.preprocessing import PolynomialFeatures
from sklearn.linear_model import LinearRegression
from sklearn.pipeline import make_pipeline
from sklearn.metrics import mean_squared_error

xs = rng.uniform(0, 1, 30);  ys = np.sin(2*np.pi*xs) + rng.normal(0, 0.3, 30)   # training data
xt = rng.uniform(0, 1, 200); yt = np.sin(2*np.pi*xt) + rng.normal(0, 0.3, 200)  # unseen test data

for d in (1, 3, 9, 15):
    m = make_pipeline(PolynomialFeatures(d), LinearRegression()).fit(xs[:, None], ys)
    tr = mean_squared_error(ys, m.predict(xs[:, None]))
    te = mean_squared_error(yt, m.predict(xt[:, None]))
    print(f"degree {d:2d}: train error {tr:8.3f}   test error {te:10.3f}")

# degree  1: train error    0.338   test error      0.288
# degree  3: train error    0.067   test error      0.096
# degree  9: train error    0.029   test error      0.175
# degree 15: train error    0.024   test error 1167719.998
| Model complexity | Training error | Test error | Diagnosis |
|---|---|---|---|
| Degree 1 (too simple) | 0.338 | 0.288 | Underfitting: bad on both |
| Degree 3 (just right) | 0.067 | 0.096 | Best on unseen data |
| Degree 9 | 0.029 | 0.175 | Overfitting: training keeps improving, test gets worse |
| Degree 15 | 0.024 | over 1,000,000 | Severe overfitting: the curve thrashes between the points |
What this shows: training error only ever goes down as the model gets more flexible. If you judged by training error, you would pick degree 15 and ship a disaster. The test error tells the truth: the model that generalises best is the moderate one. This is why every training project holds back validation and test data, and why a gap between training and validation scores is the first thing to check. Fixes include more data, a simpler model, regularisation, dropout and early stopping (halting training when validation loss stops improving).
Example 3: A Complete Workflow You Can Run
Now the real thing: a small neural network that reads 8-by-8-pixel images of handwritten digits. The code shows a proper three-way split, a training run with a loss curve, an honest final test and saving the model for later.
import joblib
from sklearn.datasets import load_digits
from sklearn.model_selection import train_test_split
from sklearn.neural_network import MLPClassifier
from sklearn.preprocessing import StandardScaler
from sklearn.pipeline import make_pipeline

X, y = load_digits(return_X_y=True)
# 1. split FIRST: 60% train, 20% validation, 20% test (stratified keeps class balance)
Xtmp, Xte, ytmp, yte = train_test_split(X, y, test_size=0.2, random_state=0, stratify=y)
Xtr, Xva, ytr, yva = train_test_split(Xtmp, ytmp, test_size=0.25, random_state=0, stratify=ytmp)
print("train", len(Xtr), "validation", len(Xva), "test", len(Xte))

# 2. build a pipeline so scaling is learned from training data only
net = make_pipeline(StandardScaler(), MLPClassifier(hidden_layer_sizes=(64,), max_iter=300, random_state=0))
net.fit(Xtr, ytr)                                  # 3. train

curve = net[-1].loss_curve_                        # loss after every epoch
print("loss at epoch 1/10/final:", round(curve[0], 3), round(curve[9], 3), round(curve[-1], 4), "| epochs:", len(curve))
print("train acc", round(net.score(Xtr, ytr), 3), "| validation acc", round(net.score(Xva, yva), 3))
print("test acc (touched once)", round(net.score(Xte, yte), 3))   # 4. final exam

joblib.dump(net, "digits_model.joblib")            # 5. save the trained model
loaded = joblib.load("digits_model.joblib")
print("reloaded model gives same predictions:", (loaded.predict(Xte) == net.predict(Xte)).all())

# train 1077 validation 360 test 360
# loss at epoch 1/10/final: 2.527 0.763 0.0068 | epochs: 185
# train acc 1.0 | validation acc 0.964
# test acc (touched once) 0.964
# reloaded model gives same predictions: True
What this shows: loss fell from 2.527 in the first epoch to 0.0068 by epoch 185. Training accuracy hit 100%, while validation and test accuracy were both 96.4%. That gap of about 3.6 points is normal and tells you the model generalises well but has memorised a little. The validation and test scores agreeing is a good sign that the workflow is clean. The saved model file was only 163 KB and reproduced identical predictions after reloading, which is exactly what you need before deployment. Whole training took seconds on an ordinary CPU, with no GPU.
The same loop in a deep-learning framework
| Concept | In our NumPy and scikit-learn code | In PyTorch or TensorFlow |
|---|---|---|
| Forward pass (predict) | pred = w * x + b or .fit() |
Call the model on a batch of inputs |
| Loss | Mean squared error, logged each epoch | A loss function object such as cross-entropy |
| Gradient | Written by hand in Example 1 | Computed automatically (backpropagation) |
| Update | w -= lr * gradient |
An optimizer object (SGD, Adam) |
| Batches and epochs | Handled inside scikit-learn | Your loop iterates over data in batches, for several epochs |
| Save the model | joblib.dump |
Save the model’s weights to a file |
Learn the loop here first. Once you understand it, moving to a deep-learning framework is mostly learning the vocabulary. If you are still building your Python foundation, our guide to coding challenges for beginners gives you a practice routine, and the best coding forums guide shows where to ask for help when your training run misbehaves.
Hyperparameters Cheat Sheet
Parameters are what the model learns. Hyperparameters are the settings you choose before training starts:
| Hyperparameter | What it controls | Rule of thumb |
|---|---|---|
| Learning rate | Step size per update | Tune this first. Too high diverges, too low crawls. |
| Batch size | Examples processed per update | Larger batches use hardware better, smaller ones add helpful noise. Limited by memory. |
| Epochs | Passes over the full dataset | Use early stopping instead of guessing a number. |
| Regularisation and dropout | Penalty or randomness that fights overfitting | Increase it when validation lags far behind training. |
| Model size (layers, width) | Capacity to learn complex patterns | Start small. Grow only if both training and validation are poor. |
For search methods such as grid search, random search and Bayesian optimisation, and for the order of operations when you tune, see our guide on how to optimize AI models.
Debugging Training: What the Symptoms Mean
Training rarely works perfectly the first time. Plot training and validation loss, and read the pattern:
| What you see | Likely cause | What to try |
|---|---|---|
| Loss does not decrease at all | Learning rate too small, a bug in the data or labels, features not scaled | Test on a tiny dataset the model should memorise; check labels line up with inputs; scale features. |
| Loss shoots up or becomes NaN | Learning rate too high (Example 1), bad values in the data | Cut the learning rate by 10 times; check for missing or infinite values. |
| Training loss falls, validation loss rises | Overfitting (Example 2) | Early stopping, more data, regularisation, a smaller model. |
| Both training and validation are poor | Underfitting, weak features, or too little training | Better features, a larger model, longer training, lower regularisation. |
| Great test score, poor results in real use | Data leakage or a test set that does not match reality | Rebuild the split, remove duplicates, test on fresh real data. |
| Accuracy stuck at the share of the biggest class | Class imbalance; the model learned to always guess the majority | Track precision and recall, weight classes, resample. |
| Validation score jumps around between runs | A small validation set or random variation | Use cross-validation, fix random seeds, enlarge the validation set. |
The most useful debugging trick: try to overfit a tiny sample of 10 to 20 examples. A healthy training setup can drive the loss to nearly zero on a tiny set. If it cannot, the problem is in the code, data or labels, not in the model’s capacity.
Training and Fine-Tuning Language Models
Large language models are trained in stages, and understanding them shows why you almost never train one yourself:
| Stage | What happens | Who does it |
|---|---|---|
| 1. Pretraining | The model learns to predict the next piece of text across enormous unlabelled datasets, which teaches language, facts and patterns. | Large labs and well-funded companies |
| 2. Supervised fine-tuning | The model learns from examples of good instructions and answers, which turns a text predictor into a helpful assistant. | Labs, and anyone adapting an open model |
| 3. Preference tuning | The model is pushed toward answers humans prefer, using methods such as reinforcement learning from human feedback. | Labs; also some teams with preference data |
| 4. Domain fine-tuning | Your own examples teach a pretrained model your task, tone or format. | You |
Your realistic job is stage 4. Updating every parameter of a large model is memory-hungry, so use parameter-efficient fine-tuning. LoRA freezes the original model and trains small adapters, and in the original GPT-3 experiments it cut trainable parameters by about 10,000 times. QLoRA adds a 4-bit base model, which let a 65-billion-parameter model be fine-tuned on a single 48 GB GPU. Our guide on how to optimize AI models includes the memory math and the decision between prompts, retrieval and fine-tuning. When your fine-tuned model is part of an automated workflow, see AI agents for business for how to roll it out safely.
How Much Compute Does Training Need?
Two simple rules let you estimate the cost of training a dense transformer language model before you spend anything:
Compute-optimal data ≈ 20 training tokens per parameter (Chinchilla’s finding; an independent replication estimated about 26).
def flops(params, tokens):  return 6 * params * tokens
def gpu_hours(f, effective_tflops=150):  return f / (effective_tflops * 1e12) / 3600

for name, n, d in [("125M model", 125e6, 20*125e6), ("1.3B model", 1.3e9, 20*1.3e9),
                   ("7B model", 7e9, 20*7e9), ("GPT-3 (175B, ~300B tokens)", 175e9, 300e9)]:
    f = flops(n, d)
    print(f"{name:28} tokens {d:9.2e}  FLOPs {f:9.2e}  GPU-hours: {gpu_hours(f):10,.0f}")

# 125M model                   tokens  2.50e+09  FLOPs  1.88e+18  GPU-hours:          3
# 1.3B model                   tokens  2.60e+10  FLOPs  2.03e+20  GPU-hours:        376
# 7B model                     tokens  1.40e+11  FLOPs  5.88e+21  GPU-hours:     10,889
# GPT-3 (175B, ~300B tokens)   tokens  3.00e+11  FLOPs  3.15e+23  GPU-hours:    583,333
| Model | Training tokens | Compute (FLOPs) | GPU-hours at an assumed 150 TFLOPs effective |
|---|---|---|---|
| 125 million parameters | 2.5 billion | 1.9 × 10¹⁸ | about 3 |
| 1.3 billion | 26 billion | 2.0 × 10²⁰ | about 376 |
| 7 billion | 140 billion | 5.9 × 10²¹ | about 10,900 |
| GPT-3 (175 billion) | about 300 billion | 3.2 × 10²³ | about 583,000 |
What this shows: the 150 TFLOPs figure is an assumption for what a modern accelerator sustains in practice, and real efficiency varies, so treat the GPU-hours as an order of magnitude. The pattern is the point. A 125-million-parameter model trains in hours, a 7-billion-parameter model needs about ten thousand GPU-hours, and a GPT-3-scale model needs more than half a million. The 6ND rule gave 3.15 × 10²³ operations for GPT-3, which matches the figure its authors reported. Note too that GPT-3 saw only about 1.7 tokens per parameter, far below the Chinchilla ratio, which is why later models train smaller networks on more data.
Energy follows compute. Training GPT-3 was estimated at about 1,287 megawatt-hours, and our guide to how much energy AI uses explains why running a model (inference) usually adds up to more than training it.
Tools and Hardware
Snapshot: October 2026. Tools change quickly, but the categories stay stable.
| Need | Examples | Best for |
|---|---|---|
| No-code training | Google’s Teachable Machine; AutoML services such as Google Vertex AI and AWS SageMaker Autopilot | Learning the idea, quick prototypes, teams without ML engineers |
| Classic ML in code | scikit-learn, XGBoost | Tabular data, baselines and small models, on a laptop CPU |
| Deep learning | PyTorch, TensorFlow with Keras | Images, text, audio and custom neural networks |
| Fine-tuning language models | Hugging Face Transformers with parameter-efficient fine-tuning libraries; hosted fine-tuning from model providers | Adapting open or hosted language models to your task |
| Experiment tracking | MLflow, Weights & Biases, or a plain spreadsheet | Logging settings and results so wins can be reproduced |
| Compute option | Good for |
|---|---|
| Your laptop (CPU) | Everything in Examples 1 to 3, and most tabular business models. |
| Free notebook services (Google Colab, Kaggle) | Learning deep learning and small fine-tuning jobs with limited GPU access. Quotas change, so check each service’s page. |
| Rented cloud GPUs | Serious fine-tuning and mid-size training. Pay by the hour, so shut machines down when idle. |
| Multi-GPU clusters | Pretraining large models. This is lab and enterprise territory. |
Evaluate Before You Trust
Training produces a model. Evaluation tells you whether it is any good. Follow four rules: score on the untouched test set once, compare with your baseline, report the right metric for the cost of errors (accuracy misleads when classes are imbalanced) and break results down by group and case type. A 96% score on 360 test cases still carries uncertainty of a couple of points either way. For the full method, including confidence intervals, golden datasets and tests for language models, read our guide on how to measure AI performance.
Deploy and Monitor
A model that only exists in a notebook delivers no value. Before launch:
- Save and version the model together with the data version, code and settings that produced it, so you can reproduce or roll back.
- Serve it behind a simple API or inside your application, and measure real latency and cost.
- Monitor quality, input drift and cost after launch, and sample live outputs for human review.
- Plan retraining. The world changes, so schedule retraining when performance drifts.
Deployment is where many projects stall, which is why companies hire forward deployed engineers to fit models into real workflows; see our guide to what a forward deployed engineer is. After launch, tools from our guide on optimizing AI models help cut serving cost and latency.
Training Responsibly
| Area | What to do |
|---|---|
| Data rights | Train only on data you have the right to use. Check licences and terms for scraped or purchased data. |
| Privacy | Remove or anonymise personal data, collect only what you need and follow data-protection law. |
| Fairness | Evaluate separately for each group the model affects, and do not rely on one overall score. |
| Documentation | Write down what data and settings produced the model, its intended use and its known limits. |
| Energy | Start small, fine-tune instead of training from scratch and avoid wasteful repeat runs. |
Common Mistakes
| Mistake | Better practice |
|---|---|
| Training from scratch when fine-tuning or prompting would do | Climb the ladder: prompt, retrieve, fine-tune, and only then train. |
| No baseline | Measure a simple method first so you know what “good” means. |
| Splitting after preprocessing | Split first, and fit scalers and encoders on training data only. |
| Judging by training accuracy | Judge by validation and test results (Example 2). |
| Tuning on the test set | Tune on validation data and open the test set once. |
| Spending months on the model and days on the data | Invest in data quality and labelling first. |
| Reporting accuracy on imbalanced data | Use precision, recall and the cost of each error type. |
| Changing many things at once | Change one thing per experiment and log it. |
| Not saving the data and code version with the model | Version everything so results can be reproduced. |
| Treating launch as the end | Monitor, and plan retraining. |
Common Myths About Training AI Models
| Myth | Reality |
|---|---|
| “You need a supercomputer to train an AI model.” | Examples 1 to 3 ran in seconds on a CPU. Only frontier language models need huge clusters. |
| “More data always fixes it.” | Quality matters as much as quantity, and the LIMA study showed 1,000 curated examples can go a long way. |
| “100% training accuracy means a perfect model.” | Our network scored 100% on training data and 96.4% on new data. Only unseen data counts. |
| “A bigger model is always better.” | Degree 15 had the lowest training error and a test error over a million. Match capacity to data. |
| “Training is the hard part of an AI project.” | Data, evaluation and deployment usually take most of the effort. |
| “Once trained, the model stays good.” | Real-world data drifts, so models need monitoring and retraining. |
Mini Glossary
- Parameter: a number inside the model that training adjusts. Hyperparameter: a setting you choose before training.
- Loss: a score of how wrong the model’s predictions are; training tries to reduce it.
- Gradient descent: repeatedly stepping parameters in the direction that lowers the loss.
- Learning rate: the size of each step.
- Epoch: one full pass over the training data. Batch: the group of examples used for one update.
- Overfitting: memorising training data so performance on new data is worse. Underfitting: being too simple to learn the pattern.
- Validation set: data used to tune during training. Test set: data used once at the end.
- Fine-tuning: continuing to train a pretrained model on your own examples.
- Pretraining: the large first stage of training a foundation model on huge datasets.
- LoRA / QLoRA: memory-efficient fine-tuning that trains small adapter matrices.
- Data leakage: information from outside the training data sneaking in and inflating scores.
More plain-language definitions are in our AI terms explained glossary.
Frequently Asked Questions About Training AI Models
How do you train an AI model step by step?
Define the task and metric, set a baseline, collect and clean data, split it into training, validation and test sets, choose a model, train it by minimising loss, tune using validation data, test once on unseen data, then deploy and monitor.
Can I train an AI model on my own computer?
Yes, for classic machine learning and small neural networks, a laptop CPU is enough, as our examples show. Fine-tuning large language models usually needs a GPU, which you can rent or access through free notebook services with limits.
How long does it take to train an AI model?
From seconds for a small model on tabular data, to hours for fine-tuning a language model, to thousands of GPU-hours for a 7-billion-parameter model and hundreds of thousands for GPT-3 scale.
How much data do I need to train an AI model?
It depends. Train on 25%, 50% and 100% of your data and see whether validation scores still rise. Fine-tuning can work with hundreds to thousands of quality examples, while pretraining a language model needs billions of tokens, roughly 20 per parameter at the compute-optimal point.
What is the difference between training and fine-tuning?
Training from scratch starts with random parameters and learns everything from your data. Fine-tuning starts with a model that already learned from huge datasets and continues training it on your examples, which needs far less data and compute.
Do I need to code to train an AI model?
No-code tools such as Teachable Machine and AutoML services let you train simple models without code. For control, reproducibility and bigger projects, learn Python with scikit-learn and then PyTorch or TensorFlow.
What is overfitting and how do I avoid it?
Overfitting is when a model memorises training data and fails on new data. Avoid it with a proper validation set, more data, a simpler model, regularisation, dropout and early stopping.
What is a loss function?
A formula that scores how wrong the model’s predictions are. Training adjusts the parameters to make this score smaller.
Should I train my own LLM?
Almost certainly not from scratch. Try prompting, then retrieval, then fine-tuning an existing model with LoRA or QLoRA. Pretraining a language model costs thousands to hundreds of thousands of GPU-hours.
How do I know if my model is good enough?
Compare it with your baseline on an untouched test set using metrics that match the cost of errors, check results by group, and report the uncertainty. Then keep monitoring after launch.
How much does it cost to train an AI model?
Small models cost almost nothing. Use the 6 × parameters × tokens rule to estimate compute, divide by your hardware’s real throughput to get GPU-hours, and multiply by the hourly price. Prices change, so check your provider.
Key Takeaways
- Training means adjusting a model’s parameters to reduce a loss, one small step at a time.
- Decide whether you need to train at all: prompting, retrieval and fine-tuning are cheaper than training from scratch.
- Split data into training, validation and test sets before anything else, and touch the test set once.
- The learning rate matters: in our example 0.1 recovered the true rule, and 1.05 blew the loss up to 34 billion.
- Watch the gap between training and validation scores. Training error alone always looks good.
- Data quality usually decides the result, so invest there before tuning the model.
- For language models, estimate compute with 6 × parameters × tokens, and fine-tune with LoRA or QLoRA rather than pretraining.
- Deploy, monitor and plan to retrain, because models drift.
We update this guide as tools and techniques change, while the principles and the math stay the same. Bookmark it, and follow the AICopse AI Updates section and the AICopse homepage for daily AI coverage.
- Hoffmann et al.: Training Compute-Optimal Large Language Models (Chinchilla), 2022
- arXiv: Parameter-efficient fine-tuning survey (C = 6ND, tokens-to-parameters ratio, PEFT)
- arXiv: Compute-optimal LLMs provably generalize better with scale (6ND and the 20:1 ratio)
- The LLM Stack: Scaling laws, compute and the 6ND rule
- LifeArchitect: Chinchilla data-optimal scaling laws in plain English (includes Epoch AI replication)
- Hu et al.: LoRA, Low-Rank Adaptation of Large Language Models
- Dettmers et al.: QLoRA, Efficient Finetuning of Quantized LLMs
- Zhou et al.: LIMA, Less Is More for Alignment
- Patterson et al.: Carbon Emissions and Large Neural Network Training (GPT-3 energy estimate)
- eWeek: How to train an AI model, a foundational guide (lifecycle and governance)
- Label Your Data: How to train an AI model (AutoML options)
- scikit-learn documentation
- Hugging Face Transformers documentation
Leave a Reply